Smoke testing is a small set of checks that proves the build’s most critical functions work, so deeper testing is worth starting. Sanity testing checks a narrower area, usually a specific change or fix, to confirm it behaves rationally. Regression testing re-runs the broad suite to confirm that changes did not break existing features.
Smoke vs sanity vs regression testing at a glance
| Smoke | Sanity | Regression | |
|---|---|---|---|
| Question it answers | Does the build work at all? | Does this change or area behave sensibly? | Did anything that worked before break? |
| Scope | Critical paths only (Priority 1) | Narrow and deeper, around one feature or fix (Priority 2) | Everything, or everything that matters (Priority 1, 2, 3) |
| When it runs | Every build or deploy | After a change, before the full run | Before a release, nightly or on larger changes |
| Size | Smallest | Small to medium | Largest |
| Typical duration | Minutes | Minutes | Longest, so split and run in parallel |
| Automate it? | Yes, always | Yes where the area is stable | Yes, this is where automation pays back most |
| If it fails | Reject the build | Send the change back | Investigate which change caused the regression |
A caveat on the words. They are used loosely. The ISTQB glossary defines a smoke test as “a test suite that covers the main functionality of a component or system to determine whether it works properly before planned testing begins”, and lists sanity test as a synonym. Many teams, including mine, still keep them apart because the split is useful: smoke is the shallow gate, sanity is the focused check. If your team uses the terms differently, agree on one definition and write it down. The names matter less than everyone knowing which suite answers which question.
As a test suite grows, the problems pile up: long execution time, flaky tests, duplicated test cases. I came across a Reddit discussion about test types, and a question stuck with me. Why not categorize the tests and run them group by group instead of in one long run? We keep the coverage, and we ship faster.
Types of end-to-end tests
For E2E tests, I sort them into three groups:
- smoke testing,
- sanity testing,
- regression testing.
Here is each of the three. For regression testing in general, this guide is a good start.
What is smoke testing?
Smoke testing is a small set of E2E tests that covers the most critical functionality of the application (Priority 1 scenarios). It checks that the application is stable enough to continue with further testing. It works like a general health check.
Characteristics:
- It covers critical functionalities (Priority 1 scenarios).
- The objective is to verify the “stability” of the application.
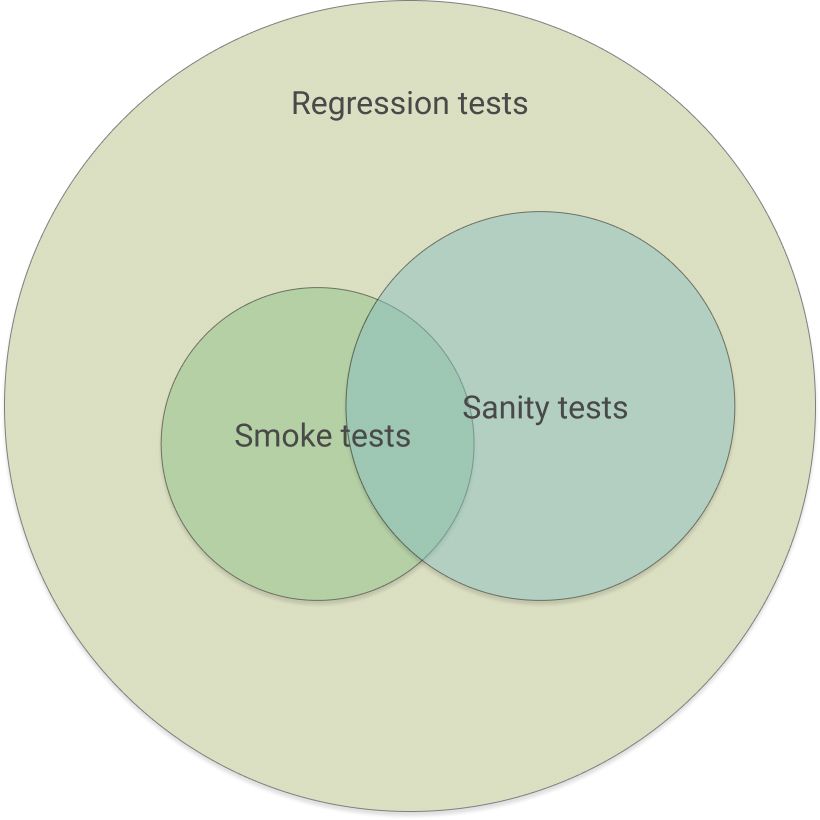
- It’s a subset of regression tests.
- A failure means instant rejection of the build.
Smoke tests should confirm the application works and delivers business value. An example scenario:
- [Netflix.com] User can log in, choose a series or movie and start watching.
What is sanity testing?
Sanity testing is a set of E2E tests that checks more detailed functionality (Priority 2 scenarios) to verify the “rationality” of the application before further testing. Think of it as a detailed health check.
Characteristics:
- It covers more specialized user actions (Priority 2 scenarios).
- The objective is to verify the “rationality” of the application.
- It’s a subset of regression tests.
An example scenario:
- [Netflix.com] User can search for movies using the search bar.
Sanity tests may share some test cases with smoke tests, but the two groups differ.
What is regression testing?
Regression testing is the full set of E2E tests that verifies every existing feature of the application (Priority 1, 2 and 3 scenarios). The ISTQB glossary defines it as testing a previously tested program after modification, to make sure defects have not been introduced or uncovered in unchanged areas. A passing run tells you everything still works.
Characteristics:
- It covers all the important and less important parts of the application.
- The objective is to verify every existing feature.
- The test cases should be well documented.
An example scenario:
- [Netflix.com] User can open “more information” about a series or movie and choose a genre.
How many tests in each type?
Regression tests > sanity tests > smoke tests.
The image below shows how the sets intersect.
How to arrange a CI/CD deployment process by test type
The most important tests are the ones that protect business value, so those must run on every deploy. Less important ones can run less often. Based on that, you can design the deployment process.
Automated testing in CI/CD brings a challenge: you don’t want the pipeline to be long. So you categorize the tests and run each group at a different time.
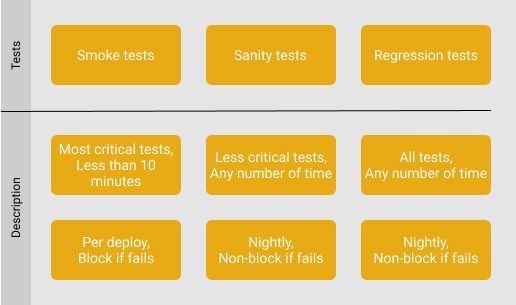
In this setup only smoke tests run with each application deploy. That way we always know the most important functionality works.
Example: tagging and scheduling the three suites
The schedule below is an example, not a recommendation for your team, and not a description of a specific project. Adjust it to how often you release and how long your suites take.
| Suite | Trigger | Why |
|---|---|---|
| Smoke | Every push and pull request, and after every deploy | Fast feedback, blocks a broken build |
| Sanity | Pull requests that touch the related area | Checks the change before merge |
| Regression | Nightly and before a release | Slow, so it runs off the critical path |
In Playwright you can tag tests and select them by tag (I ran this on Playwright 1.64):
import { test, expect } from '@playwright/test';

test('user can log in', { tag: '@smoke' }, async ({ page }) => {
  await page.goto('/login');
  // ...
});

test('user can search for a movie', { tag: '@sanity' }, async ({ page }) => {
  // ...
});
npx playwright test --grep @smoke        # smoke suite
npx playwright test --grep "@smoke|@sanity"
npx playwright test                       # full regression
And a GitHub Actions workflow that wires the schedule from the table:
name: e2e
on:
  push:
  pull_request:
  schedule:
    - cron: '0 2 * * *' # nightly regression, 02:00 UTC

jobs:
  smoke:
    if: github.event_name != 'schedule'
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-node@v4
        with: { node-version: 22 }
      - run: npm ci
      - run: npx playwright install --with-deps chromium
      - run: npx playwright test --grep @smoke

  regression:
    if: github.event_name == 'schedule'
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-node@v4
        with: { node-version: 22 }
      - run: npm ci
      - run: npx playwright install --with-deps
      - run: npx playwright test
Once regression gets long, split it across machines. I wrote about that in the importance of CI/CD and parallelisation. If you also wonder where UI, API and performance checks fit next to these three, see the taxonomy of UI, API, screenshot and performance testing.
Summary
The more tests you have, the harder they are to maintain, and running all of them after every deployment takes too long. Split into categories, the suite is faster to run and you keep the coverage you need.
You don’t have to use smoke, sanity and regression. You can divide tests by criticality level, for example. What matters is that CI/CD depends on the results of the right tests, so critical functionality is checked on every deploy. If you are choosing what to automate first, start with regression.